Budget-Aware Compression Pipeline for Single-GPU LLM Inference: Methods, Trade-offs, and Coupling Effects
GroundLM 2026 (EMNLP 2026 Workshop)
∗ denotes equal contribution and † denotes the corresponding author.
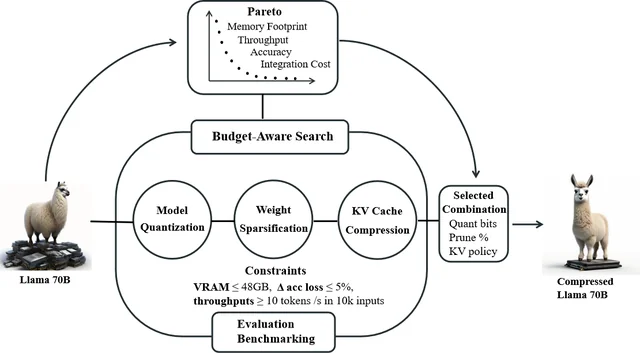
This work studies how pruning, quantization, and KV-cache compression interact, and combines them to run a 70B model with 10k-token prompts on a single A40.
Citation
Hongyu Yu and Yifei Shen. 2026. Budget-Aware Compression Pipeline for Single-GPU LLM Inference: Methods, Trade-offs, and Coupling Effects. In Proceedings of the 1st Workshop on Grounding Language Models: Learning Faithfully and Efficiently (GroundLM 2026), pages 911-922.